scrm_entry
Theo Laurent, 2026 — on hic et nunc
Ed. 1/5
Description
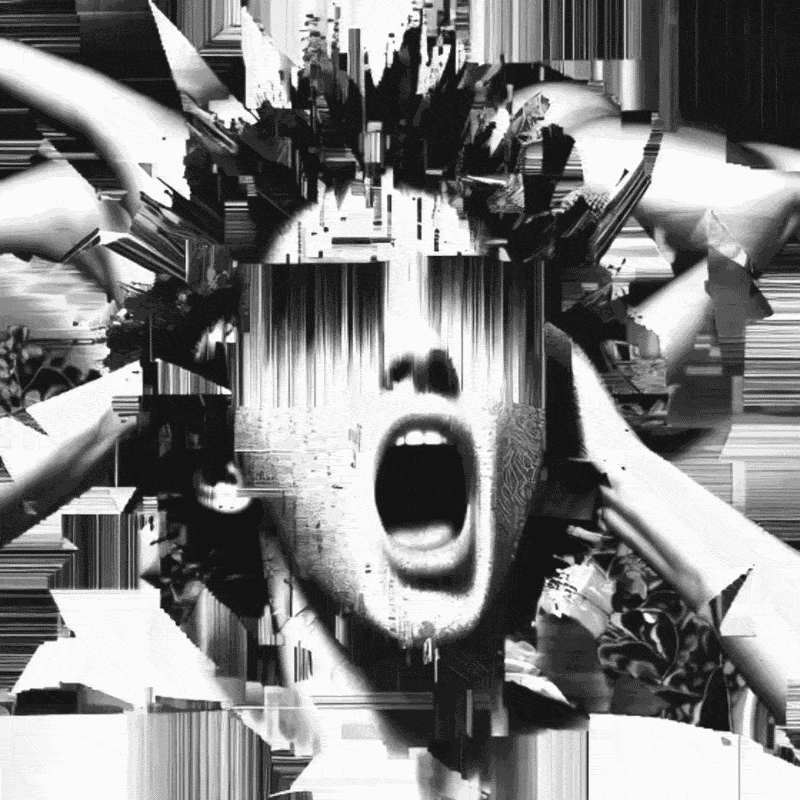
System capture of a vocal event. Form deconstruction into horizontal and vertical components. Low-bit depth rendering of facial features. 0% color saturation. 100% data density.
On-chain
Market
Provenance
Collectors