positional_encoding
sweetp, 2021 — on hic et nunc
Ed. 1/22
Description
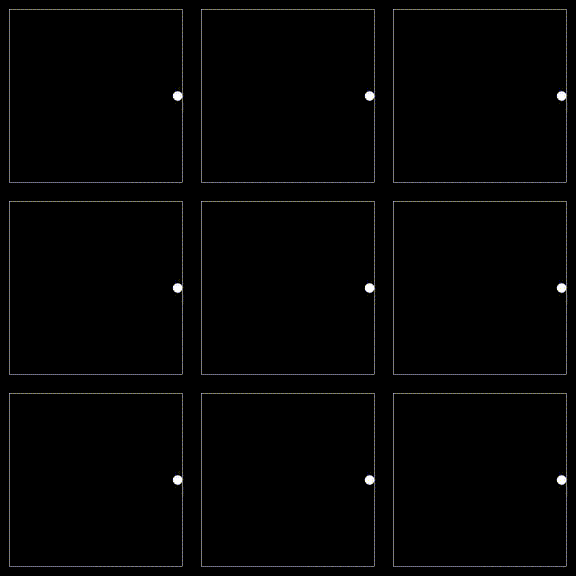
Unlike a recurrent neural network, a Transformer does not have state, and therefore is not sensitive to the passage of time. Information about time (e.g. a token's location in a sequence) is provided explicitly by adding a "positional encoding" vector to the network's input.
In "Attention Is All You Need" — the paper that introduced the Transformer — each dimension of the input vector is associated with a clock of a different speed. The cosine and sine of the angle of the clock's hand are added to the input, providing a sense of time without the need for state.
On-chain
Market
Provenance
Collectors